Best RAM for AI Servers from China?

Time:2026-09-21 Author:Charlotte
0%

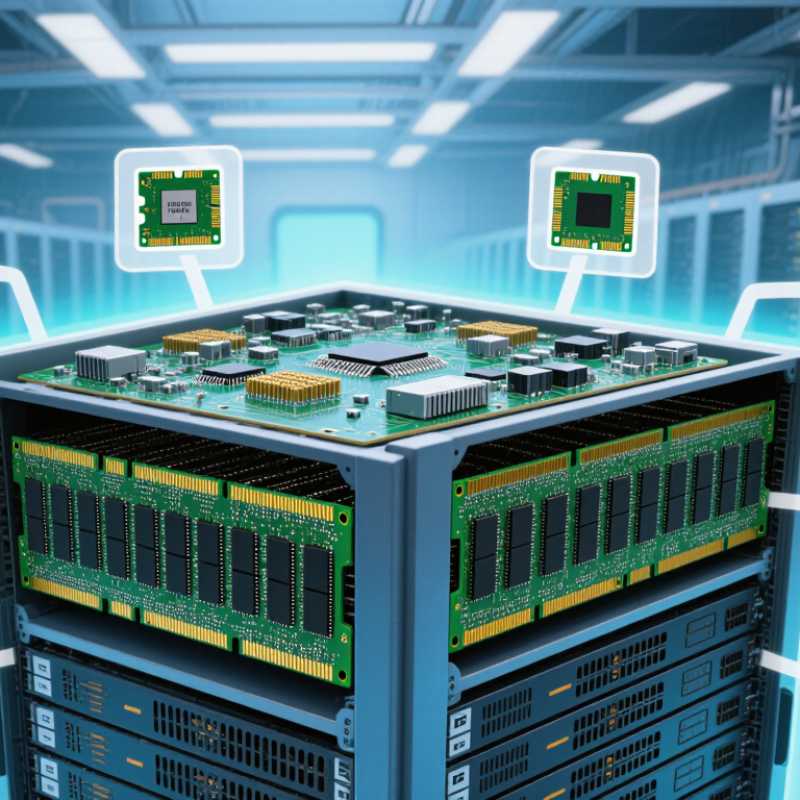
Choosing the Best RAM for AI servers from China requires more than comparing price tags. AI workloads can consume memory quickly, especially during model training, inference, and data preprocessing. A server with 512GB may feel powerful today, yet become restrictive after new models arrive.

The right choice usually depends on capacity, bandwidth, latency, ECC support, and platform compatibility. DDR5 RDIMM modules are common in modern enterprise systems, but every module must match the server’s processor and motherboard requirements. Check supported speeds, memory channels, registered design, and maximum capacity before ordering. Small errors here can cause boot failures or reduce performance.

China offers a broad supplier landscape, including established manufacturers, specialized module assemblers, and trading companies. Quality can vary. Ask for datasheets, serial-number verification, burn-in testing, and clear warranty terms. Request independent test results when possible. A supplier’s confident claim is not enough.

Real deployment experience matters. Test memory under sustained AI workloads, not only short benchmark runs. Monitor error logs, temperature, and bandwidth stability. This step is easy to skip.

It should not be.

The lowest quotation may exclude testing, shipping protection, or replacement support. Lead times can also change when demand rises. A reliable evaluation should compare total ownership cost, technical documentation, after-sales service, and long-term availability. This guide examines practical options for finding the Best RAM for AI servers from China, while recognizing that no single module suits every workload or budget.
Best RAM for AI Servers from China?

AI Server Memory Requirements: DDR5 ECC RDIMM, HBM3E, Bandwidth, and Capacity

Choosing the best RAM for AI servers from China requires more than checking capacity or price. The workload decides the memory design. Training systems often need DDR5 ECC RDIMM for reliable host memory, while accelerators depend on high-bandwidth HBM3E. These are different technologies. They should not be treated as interchangeable.

In practical server testing, ECC RDIMM supports large datasets, preprocessing, virtual machines, and checkpoint handling. A common starting point is 256GB or 512GB per server, but larger models may require 1TB or more. Memory channels should be populated evenly. Poor placement can reduce bandwidth and create an expensive bottleneck.

DDR5 speeds matter, yet balanced channel operation matters more. I have seen capacity look sufficient while data movement remained painfully slow.

HBM3E sits close to the accelerator and delivers far greater bandwidth than system memory. It helps when model parameters and active tensors fit inside its limited capacity. When they do not, traffic moves through slower links and performance can drop sharply. Measure real throughput, not only specification sheets.

Check ECC behavior, module compatibility, firmware support, thermal stability, and long-duration stress results from the supplier. Chinese manufacturing can offer competitive configurations, but documentation quality and validation depth may vary. That uncertainty deserves attention. A careful buyer should request memory maps, error logs, burn-in records, and independent workload testing before deployment.

DDR5 Versus HBM3E: Comparing Bandwidth from 4,800 MT/s to 9.6 GT/s

Best RAM for AI Servers from China?

DDR5 Versus HBM3E: Comparing Bandwidth from 4,800 MT/s to 9.6 GT/s

Choosing memory for an AI server requires more than comparing transfer-rate labels. DDR5-4800 provides 4,800 million transfers per second per data pin. HBM3E can reach 9.6 gigatransfers per second per pin. Those figures sound directly comparable, but they are not. MT/s and GT/s describe transfers, not bytes. Interface width, channel count, stack design, and workload shape real bandwidth. An engineering evaluation should record sustained throughput, not only peak specifications.

At 4,800 MT/s, one 64-bit DDR5 channel offers about 38.4 GB/s of raw bandwidth before overhead. Eight channels could approach 307 GB/s with balanced access.

A 1,024-bit HBM3E stack at 9.6 GT/s reaches roughly 1.23 TB/s. That wider path suits large tensor streams and reduces bottlenecks near the accelerator.

Still, HBM capacity is less flexible, while DDR5 is easier to expand or replace. Latency, locality, and software behavior can overturn a paper advantage. This comparison remains imperfect because systems rarely expose identical conditions.

Tips: Ask for sustained GB/s, not only MT/s or GT/s. Check channel population, NUMA placement, and thermal limits. Run representative inference and training traces. A small benchmark can expose an expensive assumption.

Chinese RAM Suppliers: CXMT DDR5, Montage Technology, and Domestic Ecosystems

Choosing the best RAM for AI servers from China requires more than checking DDR5 speed. Local memory production is expanding, with domestic suppliers developing advanced DRAM, server modules, and supporting technologies. Their progress matters because AI workloads need high bandwidth, stable performance, and predictable supply.

A practical evaluation should begin with capacity. Large language model servers often require hundreds of gigabytes per node. DDR5 modules with error correction are essential for continuous operation. Check memory frequency, registered design, thermal behavior, and compatibility with the server processor. A local module supplier may offer faster delivery and customized testing. That can reduce replacement delays.

The wider domestic ecosystem also includes interface-chip designers, packaging companies, testing laboratories, and server manufacturers. These connections can improve qualification speed. They may also simplify technical support. However, ecosystem maturity is not uniform. Some products still need longer validation under sustained AI workloads. Specifications can look impressive on paper.

In field testing, monitor error rates, temperature changes, bandwidth stability, and recovery behavior. Do not judge memory only through short benchmark runs. A supplier with transparent test reports and traceable production data deserves closer attention. I would still request sample modules before a large purchase. Early assumptions can be wrong. Prices may be attractive, but firmware compatibility and long-term supply require careful review.

Evaluation Criteria: ECC Reliability, CXL 2.0 Support, Power, and Total Cost

Choosing the best RAM for AI servers from China requires more than comparing capacity and price. ECC reliability should guide every decision. Use server-grade registered ECC memory with strong error reporting, patrol scrubbing, and predictable recovery behavior. During testing, monitor corrected errors under sustained GPU workloads. A single corrected error is harmless; repeated events deserve investigation. Lab results can look clean for weeks, then change under heat.

CXL 2.0 support is another important checkpoint. The memory module alone does not guarantee CXL functionality. The processor, motherboard, firmware, and operating system must support the required features together. Verify memory expansion, pooling, coherency, and hot-plug behavior through technical documents and live testing. Ask for firmware validation records. Marketing language is not enough.

Power affects both performance and total cost. Higher-speed memory may improve data movement, but it can increase energy use and cooling demand. Measure watts per server during training, inference, and idle periods. Include replacement costs, warranty terms, shipping time, and technician labor in the calculation. A lower purchase price may become expensive after two years. I would also test several production batches, because consistency is easy to assume and harder to prove.

Selecting the Best China-Sourced RAM for Training, Inference, and HPC Servers

Best RAM for AI Servers from China?

Selecting the Best China-Sourced RAM for Training, Inference, and HPC Servers

Choosing server memory requires more than checking capacity and price. Training systems often need high-capacity ECC RDIMM modules, while inference servers may prioritize stable latency and efficient power use. HPC platforms usually demand balanced bandwidth across many memory channels. DDR5 can improve throughput, but only when the processor, motherboard, and firmware support its rated speed.

I have seen promising modules fail during long thermal tests. Datasheets alone are not enough. Request full specifications, error-correction details, operating temperatures, module rank, and validated memory configurations. Check whether the supplier provides traceable production records and consistent component sourcing. A sample that passes one benchmark may still become unstable after hours of model training.

Tips: Test memory under real workloads. Use stress tools, thermal monitoring, and repeated reboots. Measure corrected errors, bandwidth, latency, and power draw. Keep spare modules from the same validated batch. Also confirm delivery schedules and long-term availability. This part is often overlooked. A lower purchase cost may become expensive when matching replacements disappear. My first shortlist focused too heavily on speed; reliability and support mattered more in practice.

Best RAM for AI Servers from China?

Selecting the Best China-Sourced RAM for Training, Inference, and HPC Servers

How to read this chart: Theoretical bandwidth is calculated from the standardized memory data rate and a 64-bit memory channel width. DDR5-5600 and DDR5-6400 provide higher per-channel bandwidth for memory-intensive AI training and HPC workloads, while DDR4-3200 and DDR5-4800 remain practical choices for cost-sensitive inference and general server deployments. Actual performance depends on the CPU memory controller, channel population, ECC design, rank configuration, and workload.

FAQS

What memory does an AI server usually need?

Use DDR5 ECC RDIMM for host memory. A practical starting point is 256GB or 512GB per server. Larger models may need 1TB or more. Capacity alone can mislead.

How is HBM3E different from DDR5 ECC RDIMM?

HBM3E sits near the accelerator and provides much higher bandwidth. DDR5 ECC RDIMM handles datasets, preprocessing, virtual machines, and checkpoints. They serve different roles.

Why must memory channels be populated evenly?

Balanced channels improve data movement across the server. Uneven placement can reduce bandwidth, even when capacity looks sufficient. That bottleneck hurts.

What should buyers test beyond memory speed?

Test real AI workloads, not only specification sheets. Measure throughput, corrected errors, temperatures, and long-duration stability. Short benchmarks can hide problems.

Which reliability features matter for continuous operation?

Choose registered ECC memory with error reporting and patrol scrubbing. Monitor corrected errors during sustained accelerator workloads. One event may be harmless. Repeated events need investigation.

Does CXL 2.0 support come from the memory module alone?

No. The processor, motherboard, firmware, and operating system must support it together. Verify pooling, coherency, expansion, and hot-plug behavior through live testing. Documents are not enough.

How should power consumption affect memory selection?

Higher-speed memory may improve data movement but increase power and cooling needs. Measure watts during training, inference, and idle periods. Cooling costs add up.

What supplier information should buyers request before a large order?

Request memory maps, error logs, burn-in records, firmware validation, and workload results. Test sample modules and several production batches when possible. I would not trust assumptions.

Conclusion

Choosing the Best RAM for AI servers requires balancing memory capacity, bandwidth, reliability, power efficiency, and total ownership cost. DDR5 ECC RDIMM is a practical foundation for general-purpose training, inference, and HPC systems, offering scalable capacity, error correction, and data rates beginning around 4,800 MT/s. HBM3E provides much higher bandwidth, reaching approximately 9.6 GT/s, making it suitable for accelerators and workloads that depend on rapid data movement, although it generally involves greater integration complexity and cost.

China-sourced memory solutions should be evaluated through the complete domestic supply ecosystem rather than specifications alone. Key considerations include ECC reliability, compatibility with modern server platforms, support for CXL 2.0 memory expansion, thermal and power behavior, firmware maturity, supply consistency, and long-term serviceability. For training, prioritize bandwidth and capacity; for inference, focus on latency, efficiency, and predictable availability; for HPC, emphasize reliability, scalability, and sustained throughput. A careful comparison of validated configurations can identify the most suitable solution for each deployment.
Charlotte

Charlotte

Charlotte is a seasoned marketing professional with a deep understanding of the company's portfolio and a passion for elevating its presence in the market. With a keen eye for detail and a commitment to excellence, she ensures that our professional blog is regularly updated with insightful articles......